
OCR Software with Indian Languages Support
Shop desktop, server and OCR data capture solutions that have Indian Languages recognition capabilities.
Indian Languages OCR Applications
 There are plenty of languages spoken in India (Hindi, Tamil, Telugu, Gujarati, Marathi, Urdu, Sanskrit, and many others), plus there are many scripts to write on these languages (Devanagari (Nagari), Bengali, Tamil, Perso-Arabic) with regional differences. Billions of people speak these languages, amount of documents that are created on them is enormous. But the complexity of recognition of not very standardized texts and an ease of English alternative creates a very unfortunate situation with no good document management OCR to work with Indian languages.
There are several OCRs that already exist. First of all Tesseract OCR needs to be mentioned. Tesseract is open source OCR tool, that works with Bengali, Hindi, Marathi, Nepali, Sanskrit, Tamil, Telugu and Urdu. However, it is more a good base for your automation project, and it would require a lot of work of turning rather raw OCR capabilities into document management system for your company.
OCRConverter offers a Hindi (Devanagari script) online option. It is Free and easy to use, but it lacks the automation component. You would need a lot of manual labour to integrate it into your document flow, but at least it works.
Our German colleagues have created SanskritReader for Sanskrit. It is a very decent project, but created first of all for academic purposes, and without any automation features.
There are several other online options that you can easily find but most of them look abandoned and we could not really test them.
Main document automation OCR families like ABBYY, IRIS or Kofax do not support Indian languages and are not expressing any desire to include them in any future updates.
The positive side of all that is that Indian OCR field is almost uncovered and steadily growing. And there are many opportunities for talented developers (that India is famous for) to get into growing field of Indian OCR.
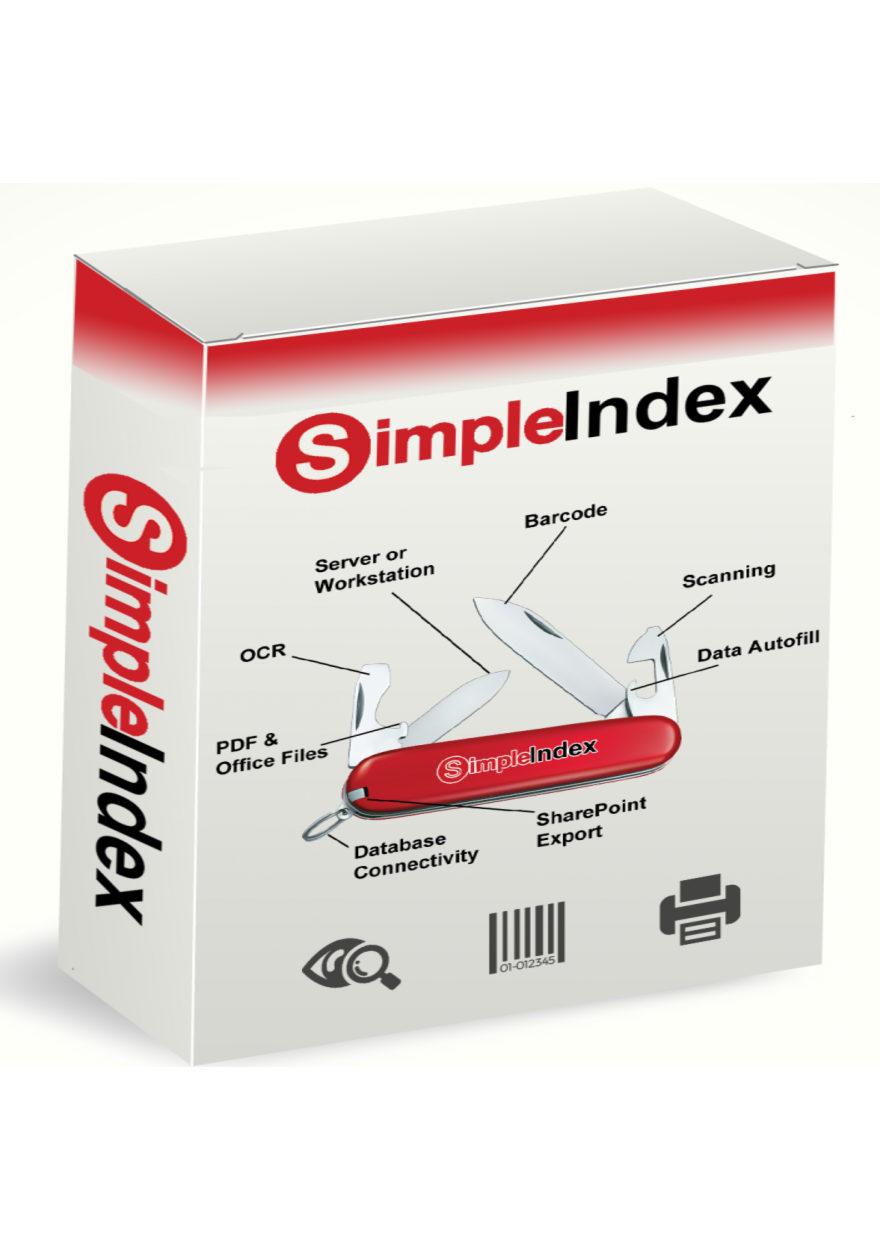
Fortunately, SimpleSoftware implemented Tesseract OCR in SimpleIndex. It means that all versions of SimpleIndex past version 9.2 (and got updated in SimpleIndex 11.2 with better version of Tesseract 5) work with Hindi, Bengali, Marathi, Nepali, Sanskrit, Tamil, Telugu and Urdu. That includes more basic versions like SimpleIndex Standard, but also products working with barcodes SimpleIndex Barcode Suite, or server OCR applications like SimpleIndex Pro Server. Even Lighter and Free version of SimpleView will work for you too.
What is OCR?
Optical Character Recognition (OCR) is a technology that converts typed, handwritten, or printed text from scanned documents and images into editable, searchable machine-readable data. Without OCR, a scanner simply takes a digital photograph of a page. Because the text in a standard image cannot be searched, copied, or modified, the data remains locked. OCR software solves this by analyzing the shapes of characters in an image and translating them into actual text that other software applications can read and process.
OCR software comes in desktop applications for personal use, batch scanning and server based OCR for businesses, and enterprise data capture applications for things like invoice processing, forms processing and hand-print recognition.
Contact Us for FREE Consultation on Your OCR Project.
Simple Software’s SimpleIndex has everything you need for document scanning, zone OCR, data validation and output to searchable PDF files, CSV or XML data, document management systems or cloud storage like SharePoint, Box and Google Drive.
The SimpleIndex document management suite includes:
- SimpleIndex comes in Standard, Barcode, OCR and Professional versions, with Server licensing available for unattended processing. FineReader OCR is included with OCR and Pro. Tesseract OCR is included with all versions. Upgraded bar code recognition and scanner drivers are included with Barcode and Pro.
- SimpleView offers folder and file based document management, OCR and editing.
- SimpleSearch uses database indexes for fast, precise document searches.
- SimpleSend automates sending of document files via secure FTP or email.
- SimpleExport converts CSV files into XML or any other text file format using XSLT.
- SimpleCoversheet creates bar code separator sheets to automate scanning and indexing.

SimpleView lets you quickly scan, organize, search and view documents stored on your hard drive or file servers. Most document management systems use a database to organize and search for files. This forces you to laboriously import files into the system, then you must rely on that system anytime you access your files. SimpleView lets you use your existing folder and filing system to find, view and annotate documents.
Share This Story, Choose Your Platform!
Not sure which OCR software you need?
Start with the task you are trying to automate, the file you need out the other end, or the language on the page. Every route below lands on products you can compare, demo and buy.