
Use robotic process automation (RPA) with OCR data capture software to create fully automated workflows that involve data entry from scanned documents, images and PDF files.
FlexiCapture and Vantage Natural Language Processing (NLP)
How to train NLP machine learning model
Today different industries face similar challenges as they seek to extract information from business documents, such as policies, e-mails and legal agreements – and most agree that is costly, time consuming and prone to errors with manual data entry.
In this video you will learn how to train NLP machine learning model in FlexiCapture to extract entities and text passages from Lease agreements.
Converting unstructured documents into structured data automatically makes this information available to your business applications while saving you time, money, and labor in the process.
Adding a field which is captured by flexilayout to a NLP-trained Document Definition
You can add the new flexible layout as additional layout to the existing one.
To do that, please open the Document Definition Editor, go to the Section’s properties and load the new layout as additional FlexiLayout.



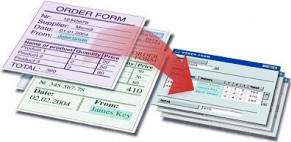
 OCR data capture is the process of using Optical Character Recognition (OCR) technology to automatically extract text and specific data points from scanned documents for business automation. While standard OCR simply converts an image of text into a readable document, OCR data capture goes a step further by identifying, isolating, and validating key information—such as dates, totals, or account numbers—and routing that structured data directly into backend business systems to eliminate manual data entry.
 Any organization that collects […]

 Enterprise Constitution Class Starship