Document Classification & Separation

In the wise words of The Offspring: “You gotta keep ’em separated!”

Automatic document separation is a common headache in document scanning and data capture applications.

When mixed batches of documents are received, it is not always easy to determine where one document ends and the next one begins.

The traditional solution for automatic document separation is to insert barcode or patch code separator pages between documents. Many scanners and scanning applications have built-in functions to read these on-the-fly and create a new file automatically each time one is found. However this approach only works with paper documents, where electronic PDF files have become far more common. And it requires printing hundreds or thousands of sheets and manually inserting them prior to scanning.

Automatic Document Separation

Modern Enterprise Data Capture solutions have the ability to define unique page elements that help identify the first and last page of any document. These work well when there is some easily identified text or form element that can be used for automatic document separation, but it doesn’t work when documents are unstructured or have a wide variety of formats, such as invoices.

For documents like invoices, Simple Software has developed intelligent separation scripts that compare extracted data from each page to determine when a new invoice starts. Multi-page invoices and attachments like BOLs and other paperwork are split automatically from large PDF files that vendors often send containing many invoice transactions.

When there is no way to determine the start of each new document automatically, Simple Software has some unique ways to automate document separation.

SimpleIndex can use OMR to separate scanned files based on a black mark placed on a corner of the first page of each file during preparation. This is much faster and better for the environment than inserting printed barcode sheets.

SimpleView lets you control-click to highlight the first page of each document in a thumbnail view, then split the PDF or TIFF file into individual documents automatically based on this selection. This is significantly faster than the drag-and-drop method used by most PDF editors.

How to configure a Batch Splitting step to split on a blank value

In PaperVision Capture a batch splitting step can be configured to meet one or more of many conditions. In some cases it may be desirable to split a batch based off a blank value within an index field. This can be achieved by using a String Comparison or Regular Expression.

The following steps should be used to configure batch splitting using a blank value. Note: These steps assume you will be splitting the batch based on an index field called “ExampleIndexField”. The index field should already exist in the job.

To split the batch on a blank value using the String Comparison type:

  1. Setup the Target Job Configuration.
  2. Add a batch split step.
  3. Add a New Condition.
    • The condition source: Capture Index
    • Choose Capture Index: “ExampleIndexField”
    • Choose Comparison Type: String Comparison
    • Leave the drop down on the equal sign “=” and leave the text box, blank.
    • Click Finish
  4. The condition should read (CI.ExampleIndexField = “”)


To split the batch on a blank value using the Regular Expression Comparison type:

  1. Setup the Target Job Configuration.
  2. Add a batch split step.
  3. Add a New Condition
    • The condition source: Capture Index
    • Choose Capture Index: “ExampleIndexField”
    • Choose Comparison Type: Regular Expression
    • Input the Regular Expression which represents any blank space characters: ^\s*$
    • Click Finish
  4. The condition should read (CI.ExampleIndexField RegEx.Match(“^\s*$”)

Reading Barcodes with Digitech PaperFlow and PaperVision Capture

Does processing barcodes “on-the-fly” make any difference in speed or recognition?

On-the-fly processing is actually a preferable way of reading barcodes since it does not noticeably decrease scan speed. The recognition will be the same whether the barcode is processed on the fly or as a post-process.


Using FlexiLayout Studio to Design Data Capture Templates

FlexiLayout: How to capture a table using Repeating Group if table header is on each page

In some cases, we might have a table that we are not able to capture correctly using a traditional method – Table element. In such cases, we usually use Repeating Group element.

But what if we come across a multi-page document that has a table header on each page?

mceclip0.png

We can use two following methods to capture such a table using the Repeating Groups.

Using Absolute search area constraints

To limit the search area to the table area so that it doesn’t capture unnecessary text outside of the table, we can use Absolute search area constraints in the Search Constraints tab.

You can measure the area with the Measure Rectangle tool.

mceclip0.png

Using nested Repeating groups

Sometimes it might be not suitable to use the Absolute search area constraints method because other tables using this layout might have different positions and lengths of elements, thus making it not convenient to use the method, because you will have to re-measure the area every single time.

In such a case, you can use the nested Repeating group method.

  1. Create the first, “main” Repeating group that will include the Table header and footer. mceclip1.png
  2. Next, create the nested RG in the first RG. The relations are as follows: mceclip2.png
  3. These are the main steps, other elements in the RG don’t need any specific settings and should be designed according to the needed results.

Additional information

FlexiLayout: Capturing a table using Repeating Group


How to reliably capture elements in FlexiLayout Studio if the image resolution can vary

When the image resolution varies, then the search area of elements based on absolute offsets can miss […]

Using ABBYY Vantage Document Skills

Processing Your First Documents with Vantage

Learn how easy it is to get started with Vantage – upload your documents and Vantage will take care of the rest.


How to Create and Train a Vantage Document Skill

Learn how to use the Vantage Skill Designer to create and train a new Document Skill with just a few sample documents.


How to Create and Train a Classification Skill in ABBYY Vantage

Learn how to use the Vantage Skill Designer to train a new Classification Skill. You need just a few samples of each document class.


How to Automate a Complete Workflow, by Creating a Vantage Process Skill


How to Edit a Document Skill

Learn how to adapt already existing skills to your specific documents and business requirements.


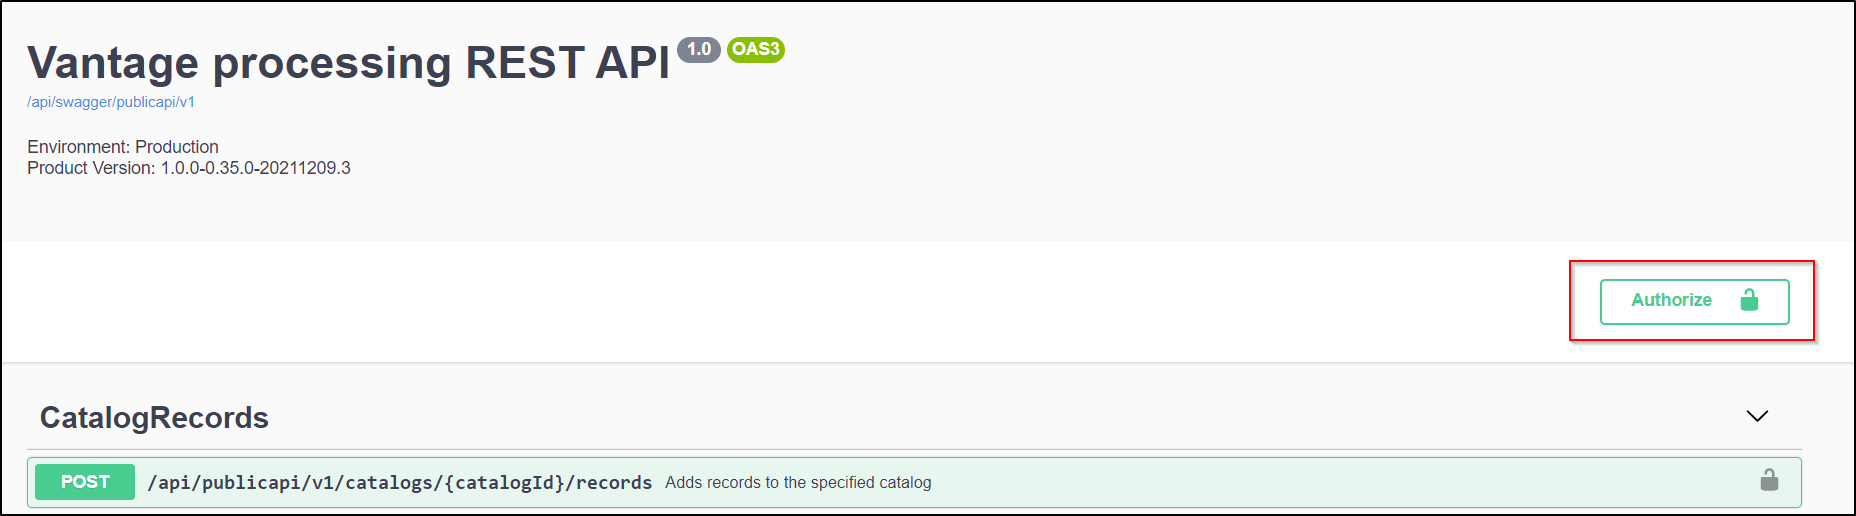
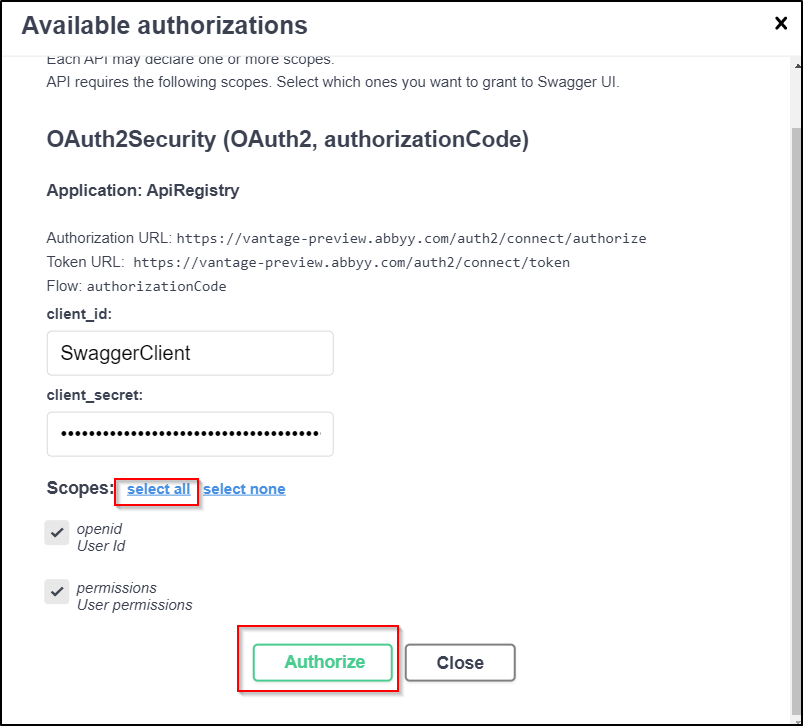
How to perform the first authentication in Vantage Swagger UI?

To get a first access token perform the initial authentification using the default client, one does not need to enter any passwords or client ID. The initial authentication is preconfigured. Just open a Swagger page (EU link or US link), click Authorize:

mceclip1.png

Select all scopes, and click Authorize again:

mceclip0.png

The password should be specified only for a custom client. A custom client can be created after the initial initialization.

References

EU Help: Getting a Tenant Identifier or US Help: Getting a Tenant Identifier

EU Help: Creating a Client or US Help: Creating a Client

Learn more at ABBYY […]

Barcode Recognition in ABBYY FineReader & FlexiCapture

Recognition of Barcodes in ABBYY technologies

ABBYY technology and products can read different barcode types.
The Document Analysis algorithms are able to locate and identify different barcodes on a document page, but of course it is also possible to “draw” a barcode block also via API.
Once the barcode region is defined/detected, it can be recognised. The API provides access to:
  • the coordinates
  • the characters
  • character confidence information
  • start/stop symbols of different barcode types,
    for barcodes of type Code 39 the start/stop symbol is the asterisk “*”
  • The barcode value can then be used for file naming.
A very common scenario is document separation based on barcodes.
    • This feature is implemented in FlexiCapture projects
    • With FineReader Engine, the developers can “cut” the page stream with custom code
    • Separation in FineReader Server
    • Separation in the ABBYY Scan Station (FineReader Server & FlexiCapture)

Tips for working with barcodes

Barcode recognition quality depends on:

  • the barcode print quality
  • settings used in the document scanning process
  • Placement of the barcode when it is manually added

In order for the barcodes to be recognized well, follow these recommendations:

  • A barcode must be separated from other text by a fairly wide white gap.
  • Barcode size and the width of its separate bars or dots must meet the following requirements:
    • The optimal barcode height is more than 10 millimetres. The size of a barcode should be less than A4 size.
    • Barcode height must be higher than the double height of a text line
    • For not-square barcodes, […]

Document Processing via Email in FineReader Server

In this video, learn how to configure a workflow for document input and processing via e-mail on FineReader Server.

See how in a few simple steps you can configure this workflow. You can even edit the e-mail subject and message. Watch how to setup usage scenario: Centralized document conversion service in this video.

From the document input to the document output, including the document processing, FineReader Server is designed to simplify, optimize and fasten your worflows. Scalable and easy to configure, FineReader Server can adapt to all your needs.


How to convert several emails from MS Outlook into PDF?

In order to convert several emails into a PDF file, you may use the virtual printer PDF-XChange 5.0 for FineReader.

Follow the steps below:

  1. Select the needed emails in MS Outlook.
  2. Press File>Print.

    File_Outlook.png

  3. Select ​PDF-XChange 5.0 for FineReader as a printer and press Print.

    virtual_printer.png

  4. Save the PDF file.


How to set up the import from the Gmail mailbox using the IMAP Image Import Profile?

  1. In your Gmail, create the folder (mailbox) that you want to import from.
  2. In your Gmail, create the folders (mailboxes) for the Exceptions and Processed emails.
  3. Enable the IMAP protocol in Gmail settings.IMAP_POP3_in_gmail.png
  4. Turn on the Less secure app access option in the Security section of Google Account Settings.Less_secure_apps_gmail_2.png
    Less_secure_apps_gmail_.png
  5. Create a new Image Import Profile (open the project in the Project Setup Station > Project > Image Import Profiles > New). Choose Hot Folder: IMAP Server.
  6. Specify the address of the IMAP server: imap.gmail.com.
  7. Click settings and specify your Gmail login and password. Choose Type of encrypted connection: SSL.

    mceclip0.png

  8. Click Browse and select […]

ABBYY Vantage

ABBYY Vantage leverages AI machine learning and a huge library of document “skills” to provide out-of-the-box data capture for all kinds of documents.

Vantage provides a simple way to implement new data capture processes without the need for programmers.

It takes the FlexiCapture platform, hosts it in the cloud, and dramatically simplifies the interface. The thousands of settings you can use with FlexiCapture to build templates are managed by the AI, giving you a simple point and click interface to create new document capture workflows.

The “Skills” library gives you pre-configured capture workflows for hundreds of the most common documents. Simply connect them to your import and export destinations and you are ready to go, saving you hours or even days of development time.

Abbyy Vantage 3.0 added a more conservative way to use AI, with using OCR first and then suppling this data for the AI functions.

PaperVision Capture Forms Magic

PaperVision Capture Forms Magic adds handwriting recognition, forms processing, invoice processing or healthcare claims forms templates and business rules to their high-volume document scanning and data capture platform.

OCR Consulting Services

OCR Experts for Any Project

Our unique team of OCR experts are equipped to help out with OCR projects of any size or complexity. We have support specialists that can remotely configure desktop solutions in a matter of minutes and expert systems integrators with years of programming, database design, and robotic process automation experience.

Desktop OCR

Batch Document Scanning and OCRUse our online store to order desktop OCR applications and our staff will be happy to answer your setup questions via email or web chat.

Remote configuration and training services using GotoMeeting are available for a low hourly rate.

Batch Scanning & OCR Servers

Data Capture Forms OCRAutomate document scanning and digital document archival processes using zone OCR, barcode recognition, database integration and other technologies.

Small business systems and single document workflows can be setup remotely via GotoMeeting, usually in just a few hours. Chat now if we’re online or leave a message to schedule a consultation.

Data Capture and Forms Processing

Advanced data extraction solutions that can turn the most complex documents into structured data ready for use in business applications. Each member of our data capture consulting team has over 10 years experience designing and implementing advanced OCR solutions.

We are the most experienced system integrator in the US for our flagship data capture platform, ABBYY FlexiCapture. We saw its potential immediately when it was introduced and now over 15 years later it is the leading data capture solution and no team is more experienced than ours at implementing it. We are the ones that other ABBYY integrators call for their most complex implementations.

While we have designed capture solutions for all types of documents, we have particular expertise in the following […]

OCR Data Capture

What is OCR Data Capture?

document OCR process automationOCR data capture is the process of using Optical Character Recognition (OCR) technology to automatically extract text and specific data points from scanned documents for business automation. While standard OCR simply converts an image of text into a readable document, OCR data capture goes a step further by identifying, isolating, and validating key information—such as dates, totals, or account numbers—and routing that structured data directly into backend business systems to eliminate manual data entry.
Many are familiar with popular desktop OCR applications designed to convert scanned images to editable documents. When this process is applied to specific areas of the document containing data fields it’s called zone OCR. But OCR data capture software is more than just simple zone OCR. Modern applications use some or all of these technologies:

Enterprise data capture systems provide interfaces for scanning, recognition, data verification and export, as well as management and monitoring tools to track large volumes of documents and data through the workflow.

Who can benefit from OCR data capture software?

messy business information made easy with ocr data captureAny organization that collects […]

Knowledge Base

The SimpleOCR Knowledge Base contains frequently asked questions and answers, technical guides and general information on a broad range of optical character recognition, handprint recognition, data capture, PDF OCR, AP invoice scanning and zone OCR applications.

Contact Us for FREE Consultation on Your OCR Project

ABBYY FlexiCapture Cloud

ABBYY FlexiCapture Cloud

ABBYY FlexiCapture Cloud delivers ABBYY’s advanced data capture platform capabilities via REST API and web interfaces. ABBYY FlexiCapture Cloud customers can rapidly configure and deliver their Content IQ solution, taking advantage of our cloud services to automate and accelerate their document-driven processes. The advanced machine learning and AI in the platform improve classification and data extraction results, enabling core processes to support better, smarter, faster decisions.

FlexiCapture Cloud enables organizations to accelerate digital transformation by complementing their automation systems with new and advanced cognitive capabilities that liberate the intelligence locked in their documents.

ABBYY FlexiCapture On-Premise

ABBYY FlexiCapture On-Premise – Distributed – Perpetual License PPY 50K Pages

ABBYY FlexiCapture is a powerful data capture and document processing solution from a world-leading technology vendor. It is designed to transform streams of documents of any structure and complexity into business-ready data. And its award-winning recognition technologies, automatic document classification, plus a highly scalable and customizable architecture, mean that it can help companies and organizations of any size to streamline their business processes, increase efficiency and reduce costs.

Invoice Processing

What is Invoice Processing?

Invoice processing software is a specialized automated solution that uses OCR data capture technology and page layout analysis to automatically extract key data from financial invoices. By applying intelligent data extraction algorithms specifically tuned for accounting workflows, the software automatically identifies, isolates, and indexes common transactional data points such as vendor names, invoice dates, total amounts, invoice numbers, and line-item details. Because invoices are among the most common documents companies need to process, these specialized applications are pre-configured to handle various layout variations, seamlessly routing the captured data into backend ERP or accounting systems without manual data entry.

Who can benefit from Invoice Processing software?

Data Capture Forms OCRAny organization that receives a large number of vendor invoices on paper can benefit from invoice processing technology. The more data from each invoice that you are hand-keying into your accounting software the more benefit you can get from each page you automate.

Accounting firms and other companies that do outsourced accounts payable processing stand to gain the most return on investment from automation. It also has the benefit of on-shoring the data entry, providing additional security and piece of mind to your customers.

A robust OCR invoice processing solution becomes justifiable when you have over 1,000 invoices per month. When dealing with smaller volumes the potential return on investment does not justify investment in an enterprise solution. However, a simple document scanning solution to digitize and store scanned invoices can still provide many benefits.

How does it lower the cost of AP processing?

There are many benefits to OCR invoice systems when it comes to AP processing that give these systems a very high return on investment.

  • Automate data entry tasks
  • Eliminate data entry errors […]

SimpleView

Application for managing and viewing scanned documents, images and PDF files.

Unlike other freeware PDF viewers, SimpleView is designed to work with many files at once instead of one at a time. The free version also supports TWAIN scanning and the ability to move, rearrange and rotate pages.

Simple Software

SimpleIndex can bring speed and efficiency to your scanning or doc filing no matter the process. Even if all you are doing is hand keying a few basic details about a document, breaking those details into individual indexes and adding tools like drop down choice lists, automatic orientation, and blank page deletion ensure a smoother, more consistent process.

Automation

Here’s where things start to get interesting. From basic tasks like splitting individual documents within at stack of pages by spotting a blank page, a specific mark, or a barcode separator to capturing index data directly from the page or looking up additional details about a document in a database, SimpleIndex has a host of powerful tools to tame your piles of paper or drives full of digital files. Let’s look at a few.

OCR

Optical Character Recognition is the ability to take a scan, which is merely a picture of a page, and turn it into words that the computer can understand and use to index your files. SimpleIndex leverages the power of ABBYY FineReader, recognized as one of the best OCR engines on the market, to accurately capture names, dates, important numbers, document types, and other details about your file. Some products have you set a box and capture whatever information happens to fall in that zone. SimpleIndex takes it further with Dynamic Zone OCR to enable you to set an oversized zone that allows for shifting of the pages between scans, but still captures just the date you need by matching against templates, lists, or even Regular Expressions (RegEx). You can also skip the zones entirely and use the full text of a page to find matches for your index data.

Barcodes

SimpleOCR | OCR Software Experts

Learn More Download Now

Document Scanners
& Scanner Parts

Accurate OCR starts with quality images. Efficient OCR starts with fast scanning. Find Document Scanners built for OCR at ScanStore.

Our Team of OCR experts is here to help! SimpleOCR is not just Freeware, we have every kind of OCR solution from PDF Converters to Enterprise Data Capture, OCR Servers and Handprint Recognition for Forms and Surveys. Live chat with an OCR specialist now or Contact Us for a consultation on your OCR project.

SimpleOCR is the popular freeware OCR Software with hundreds of thousands of users worldwide. SimpleOCR is also a royalty-free OCR SDK for developers to use in their custom applications.

SimpleIndex is OCR built for business, offering powerful batch scanning, OCR server, and data capture features with a simple user interface and affordable licensing.

If you like free stuff, freeware versions of our SimpleView Document Viewer (with Tesseract OCR), SimpleCoversheet Bar Code Printer, and SimpleExport CSV to XML Converter are also available.

If you have a scanner and want to avoid retyping your documents, SimpleOCR is the fast, free way to do it. The SimpleOCR freeware is 100% free and not limited in any way. Anyone can use SimpleOCR for free–home users, educational institutions, even corporate users.

If your documents have multi-column layouts, non-standard fonts, tables, poor quality or digital camera images, you will not have much success with applications based on free and open source engines like SimpleOCR and Tesseract. You will need a commercial OCR application to get an accurate read. Our OCR Guide compares desktop and server OCR […]

Forms Processing

What is ICR, Survey & Forms Processing?

ICR stands for Intelligent Character Recognition and is the technology that allows software to interpret hand printed text on scanned images.

Data Capture Forms OCRForms Processing Software uses ICR technology to automate data entry tasks involving hand-filled surveys, applications and forms. It provides interfaces for scanning, recognition, data verification and export, as well as management and monitoring tools to track large volumes of documents and data through the workflow.

Forms Processing also includes OCR (Optical Character Recognition) technology to recognize machine printed text, and OMR (Optical Mark Recognition) for check boxes and multiple choice bubbles.

It is also possible to use these applications to automate data collection from PDF forms, Word documents, Excel spreadsheets, and other formats used to fill out forms electronically. Many include the ability to publish forms as paper, fillable PDF and web pages simultaneously to distribute and collect data from multiple sources into one dataset.

Who can benefit from forms processing software?

Any organization that collects data on paper-based forms, surveys or applications on a regular basis can get a very high return on investment by automating the data entry with forms processing software.

You do need to have a significant number of forms to justify the expense– at least a hundred forms per month or more depending on how much data is being captured. If the data entry task can be done in under 100 man-hours then it is not a good candidate for automation with ICR software.

Organizations that have many separate departments that collect data on forms can share the budget for forms processing software by re-using it for other projects. Your current project may not be big enough to justify the expense, but when combined with one or two others it would be.

How much do […]

Document Management

Simple Document Management SystemsDocument management covers a lot of ground, from a shared folder of scanned files to a records system with audit trails and retention rules.

Whichever one you need, the step that decides whether it works is the first one: getting paper in as searchable, indexed documents instead of flat images nobody can find.

We sell both halves. Capture and OCR software indexes documents on the way in, and document management systems store, search, share and route them. We can also add OCR to the system you already run.

Contact us for a free evaluation of your project and a live demo of the software we recommend.

Small Offices and Departments

For one department or a small business, a well-organized shared folder is often all the document management you need. Batch scanning software like SimpleIndex reads barcodes and text as it scans, then names and files each document automatically, so a shared folder or SharePoint library stays searchable without anyone typing.

Desktop document management adds a viewer, search and simple organizing on top, without the security and workflow overhead of an enterprise system.

Cloud or On-Premise

A web-based system works from any computer without installing client software. A hosted one also takes the servers and upgrades off your hands.

Both of the enterprise platforms we recommend come in on-premise and cloud versions:

Records Management for Larger Organizations

Once more than a handful of people share documents, you usually need more than storage and search:

  • Access […]

Document Scanning

Document scanning software: the whole run, not just the recognition step

Feeding paper into a scanner is the easy part. What costs money is everything around it — deciding where one document ends and the next begins, straightening and cleaning the images, reading enough of each page to name and file it, checking the result, and handing it to whatever system has to hold it. A document capture platform is software that runs that sequence over a batch, unattended, and only asks for a person when something genuinely needs one.

A batch, end to end

  • Scan or import. TWAIN and ISIS scanners, watched folders, email or files already on disk — existing images are treated the same as fresh paper.
  • Separate. Barcode sheets, patch codes, page counts or a recognised value tell the software where each document starts, so a stack goes through in one pass instead of one job per file.
  • Clean up. Deskew, despeckle, crop, drop blank pages and convert to bitonal, because recognition accuracy is mostly decided before the OCR engine sees anything.
  • Recognise and index. Full-page OCR makes the document searchable; zone, barcode and AI extraction pull the handful of values that become the filename, the folder path and the database record.
  • Validate. Check a value against a database or a rule, and route only the exceptions to a person rather than having someone watch every page.
  • File and export. Searchable PDF, TIFF or text into an ECM system, a shared folder, SharePoint or a line-of-business application, with the index data written alongside as CSV, XML or a database row.

Where hybrid OCR fits, and why it matters to the bill

Indexing used to mean a template for every layout and a person fixing what the template missed. The platforms below now read the page with a conventional OCR engine on your own hardware first, […]

Applications

Why do I need OCR?

Optical Character Recognition (OCR) is a technology that converts typed, handwritten, or printed text from scanned documents and images into editable, searchable machine-readable data. Without OCR, a scanner simply takes a digital photograph of a page. Because the text in a standard image cannot be searched, copied, or modified, the data remains locked. OCR software solves this by analyzing the shapes of characters in an image and translating them into actual text that other software applications can read and process.

There is a wide variety of OCR software available. While they all share the ability to convert images of machine printed (not handwritten) text or numbers into an editable format, the various software often have different features, accuracy, prices, and language options.

You can find the various types of OCR software with a description of each below.

Users within a single department, working from home or who have a small business can simply scan their documents to a folder that is shared to everyone. In this “ad-hoc” scenario you only need some basic document scanning software to simplify and bring consistency to your filing system.

If you want to move to the next level, there are Desktop Document Management options that provide an all-in-one means for capture, storage, search and retrieval of documents. Additionally, they provide security, advanced capabilities and ease of use above that of the ad-hoc methods

And let’s not forget cloud-based options that alleviate the need to maintain storage servers or keep software up to date.

Need a simple, no frills OCR solution without spending hundreds of dollars on a professional software package? Look no further. There is a no cost, […]

2026-10-03T15:36:32-04:00Tags: , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , |
Go to Top